Semantic Similarity of Textual Data
Architecture
Research focus
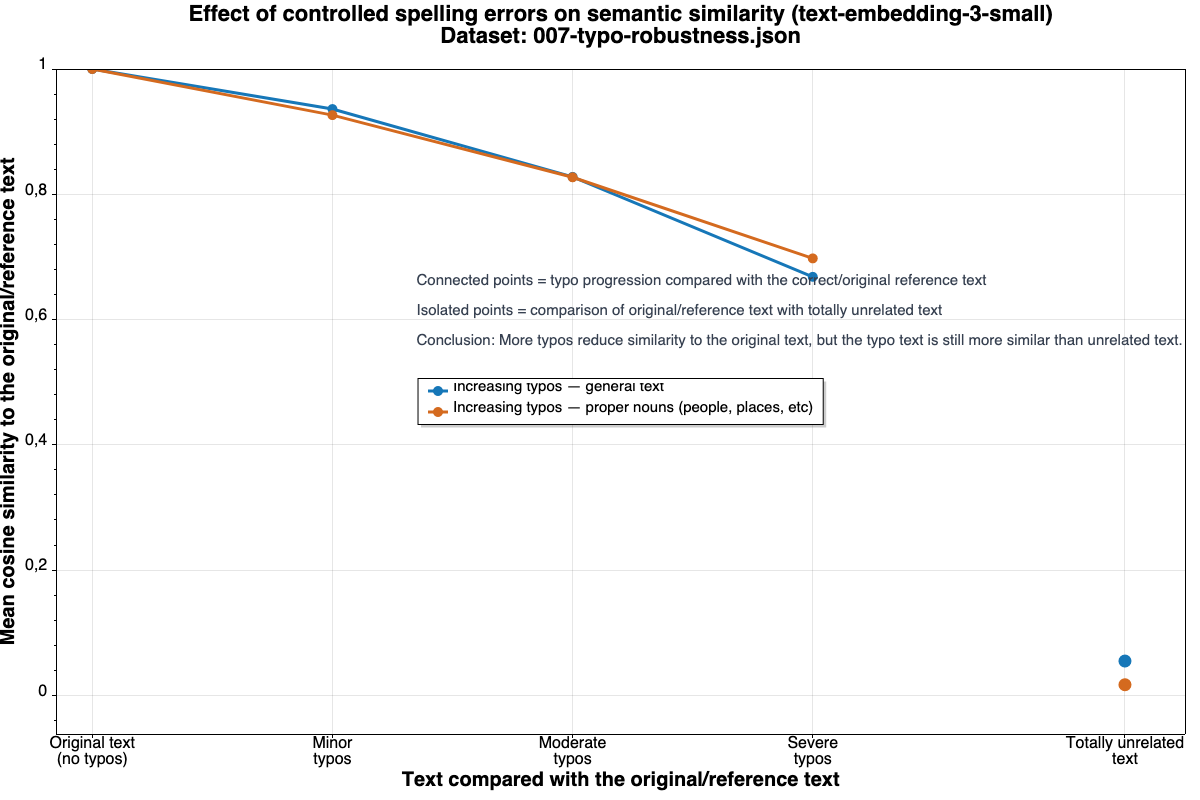
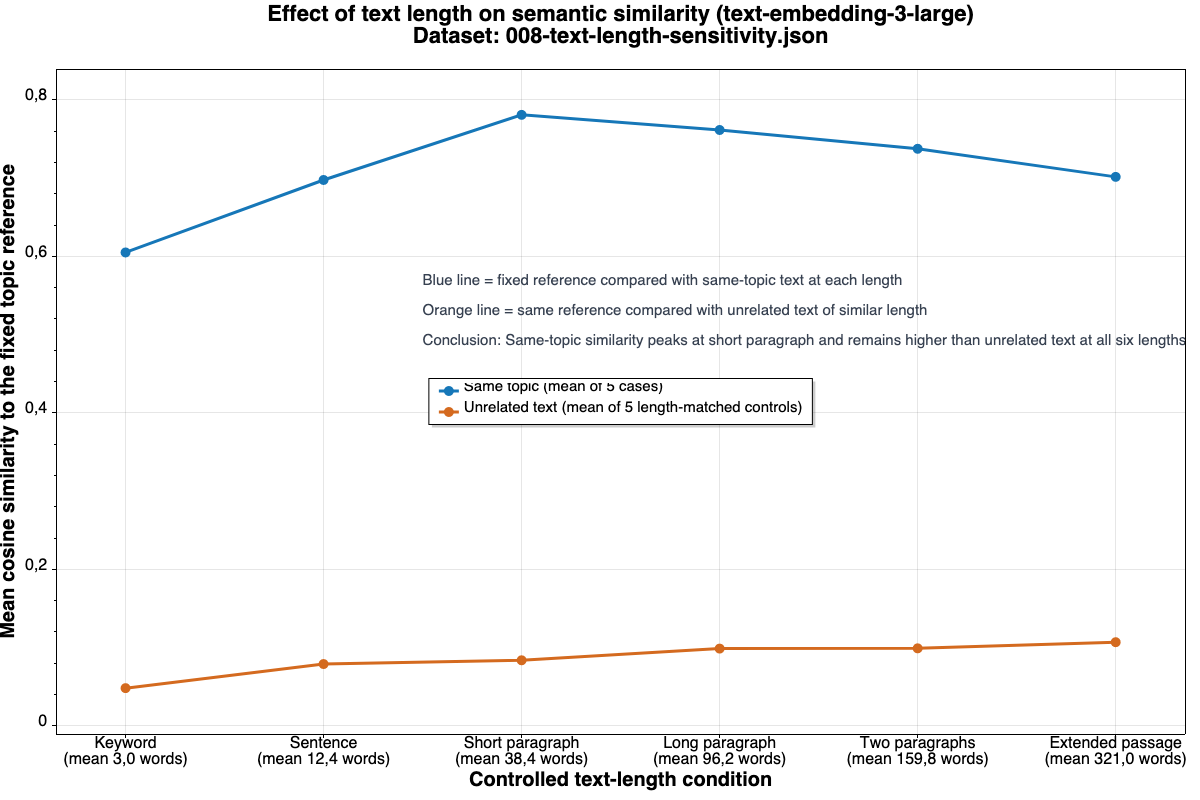
Evaluated whether embedding-based similarity remains reliable under controlled spelling errors and changes in passage length, using unrelated text as a baseline.
Implementation
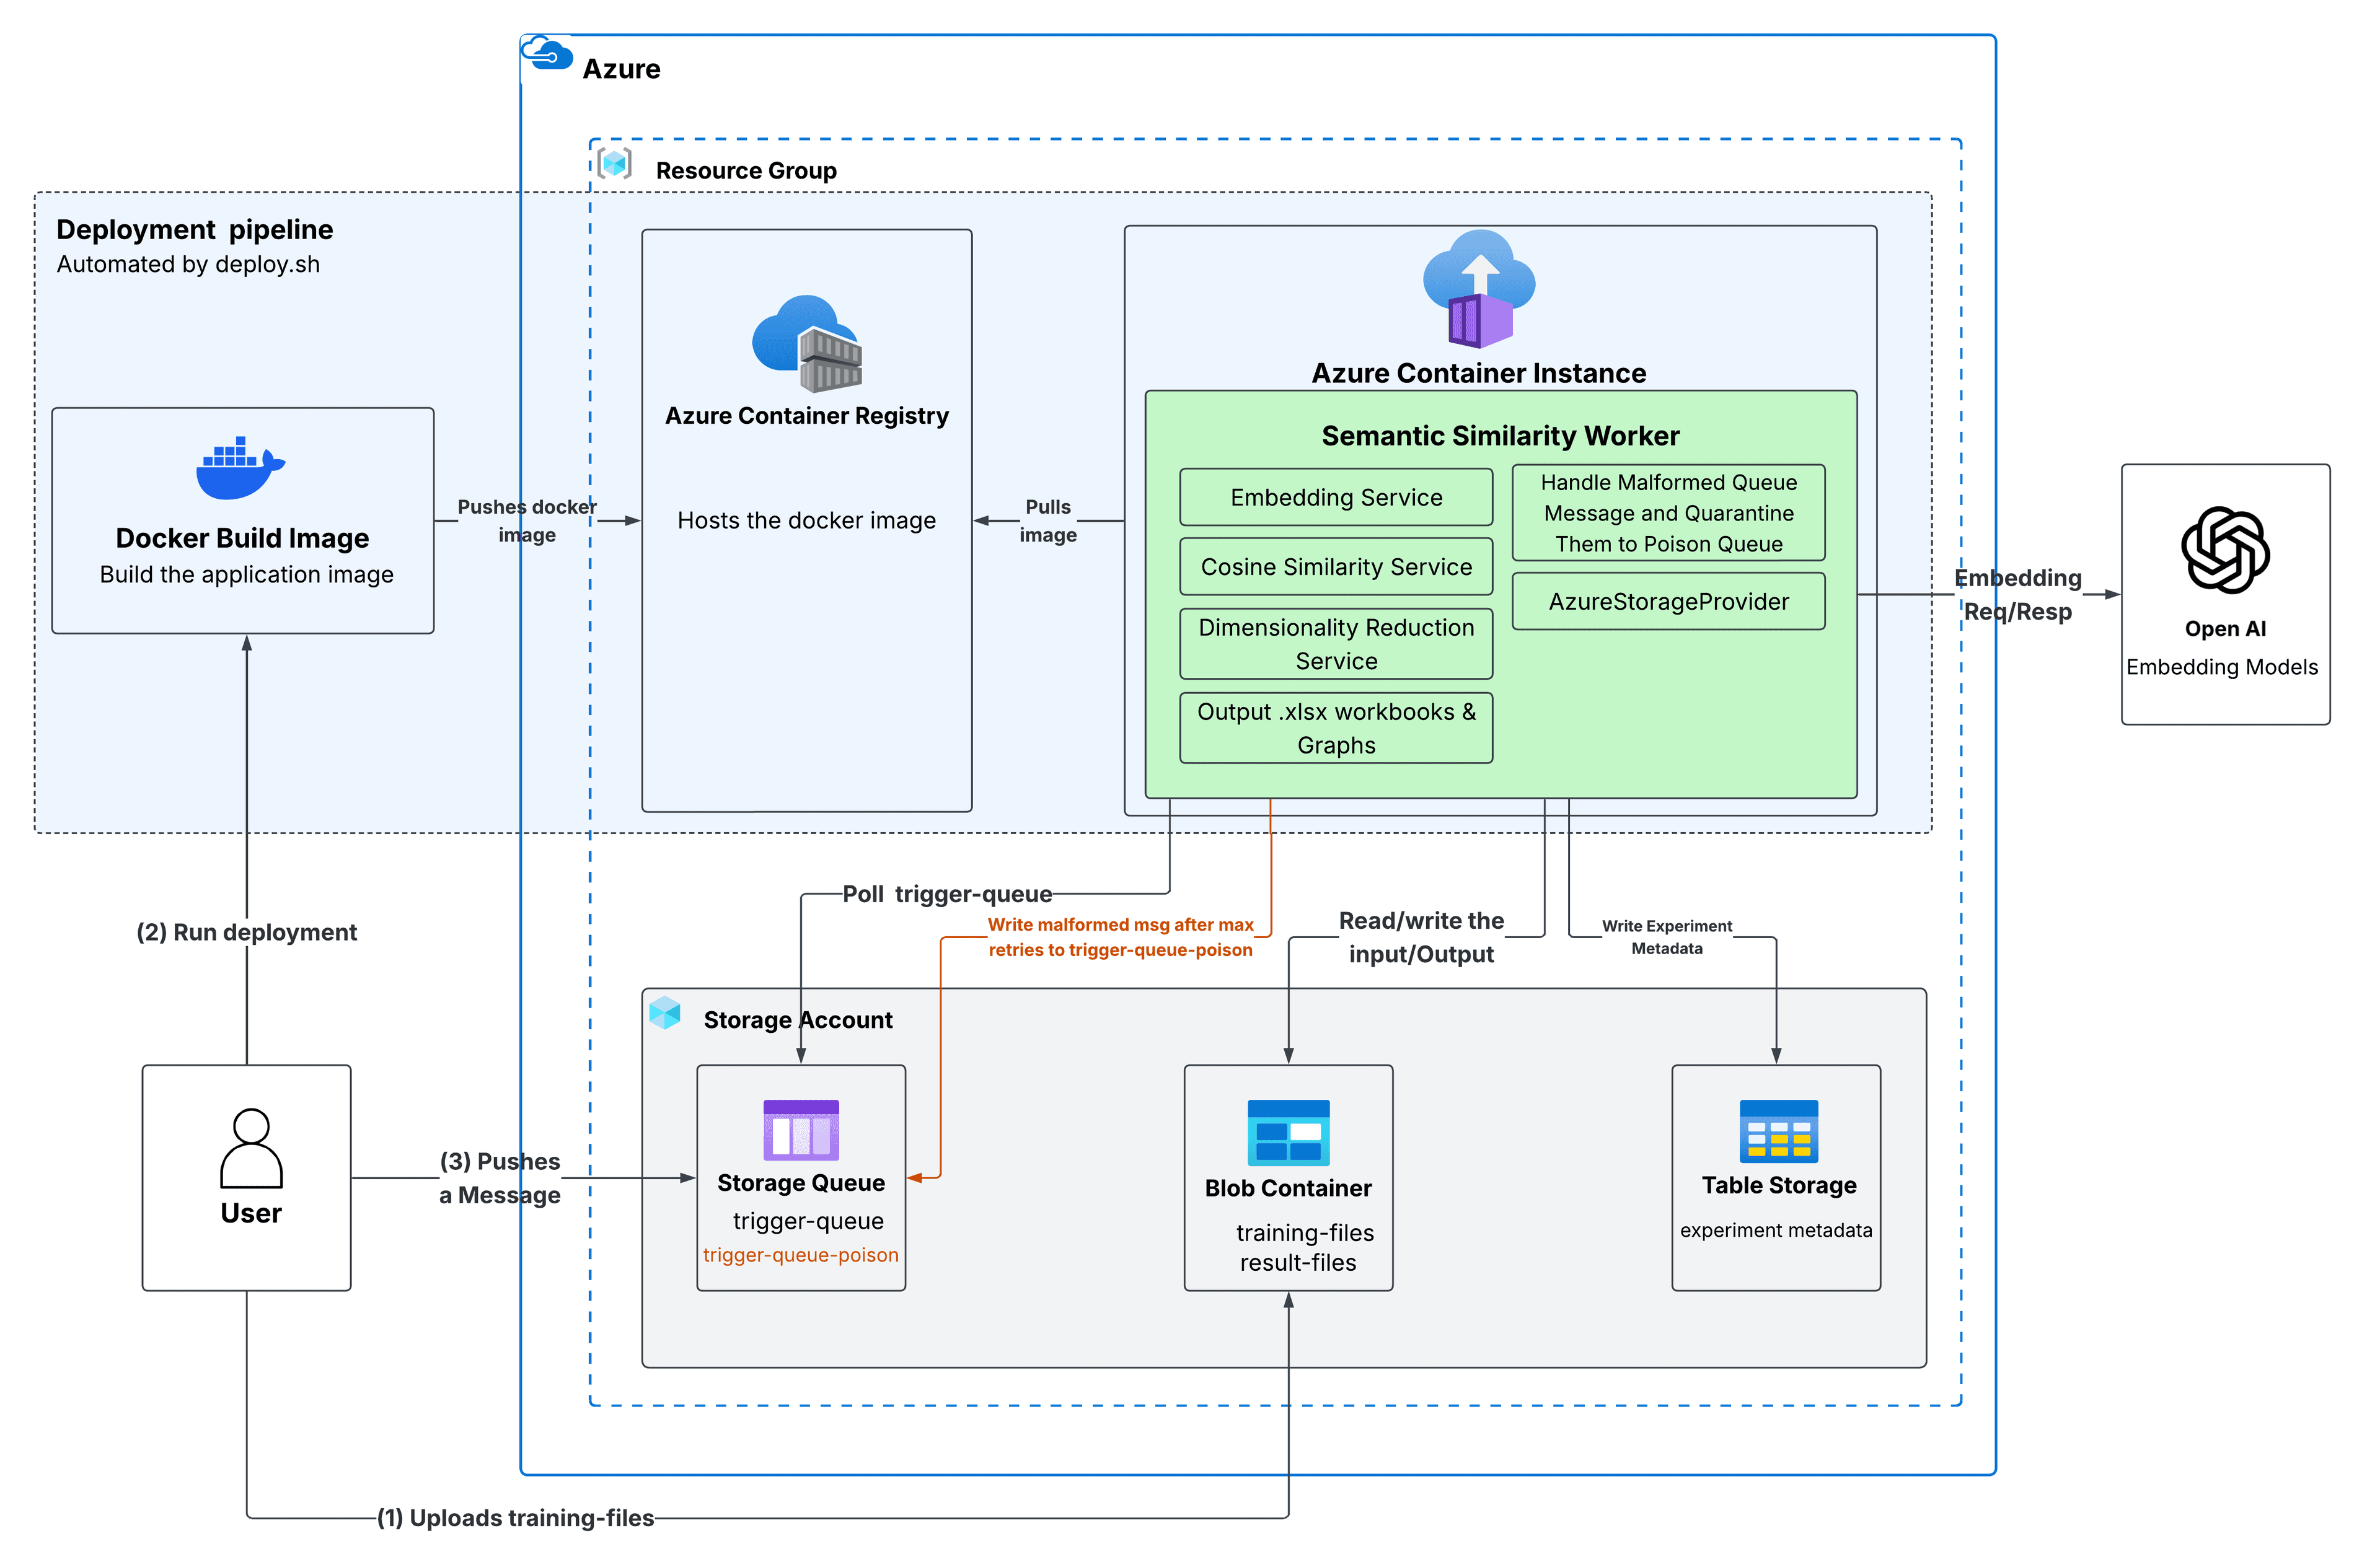
Implemented a C# worker on Azure Container Instances. Queue messages trigger experiments; the worker reads inputs from Blob Storage, calls the OpenAI API for embeddings, computes cosine similarity, and stores results and metadata in Azure Storage.
Findings
Related passages consistently scored above unrelated controls across six tested text lengths. Similarity declined as typos increased, but remained above unrelated-text scores even at the most severe tested level.
Technology
C# · Azure Container Instances · Azure Storage · OpenAI API · Docker
Selected results